For solo builders
A possible application for this research area. Paper-specific feasibility still needs a full-paper review.
A product assistant retrieves plausible documents but gives unsupported answers.
What you would change
Change one retrieval or ranking step while keeping the document snapshot fixed.
Try the idea on your product
A proposed first test. Set your budget and success criteria before running it.
Change one retrieval or ranking step while keeping the document snapshot fixed.
Compare against
Your current retrieval pipeline with identical questions and answer model.
- Locate the paper's implementation and check its license, model support, data needs, and hardware requirements. Stop here if you cannot obtain the required artifacts.
- Save a small set of representative product tasks and expected outcomes. Keep evaluation tasks out of any training or tuning, and choose quality and cost limits before running.
- Run the baseline and the proposed change on identical inputs. Keep other settings fixed and repeat paired runs to expose variation.
- Save per-task outputs, failures, timings, and all usage costs. Review regressions before expanding the test.
What to measure
Supported answers, retrieval misses, correct abstentions, index cost, and response latency.
When to keep it
Keep the change only if it meets your preselected quality and latency limits and improves the metric you care about after setup and operating costs. Otherwise retain the baseline. This is an exploration plan, not a validated recommendation.
Download test plan ↓abstract indexedPaperraft next step
Do not allocate compute yet.
This page uses the abstract and public adoption signal only. Request the deep report before relying on its recommendation.
Abstract-level screening only. Risks and infrastructure may not have been evaluated. This recommendation is not a reproduced result.- minimum test setup
- not reported
- published evidence setup
- not reported
- source-linked claims
- 0 of 1
- exposure checks
- 0 of 8
Why it was shortlisted
The technical change, research area, and reason it entered the archive.
- recommendation
- watch
- research area
- retrieval and RAG
- technical change
- Decomposed relation extraction with hard-negative sampled classifiers
- published
- 2026-10-19
The paper reports a negative result showing this decomposed classifier approach fails under realistic relational sparsity, so the reader should treat it as a cautionary evaluation finding rather than adopt it, while noting its lesson that sampled-negative validation badly overestimates exhaustive performance.
About the technical core
Equations have not been fetched yet.
When reading the methods, identify the rule, algorithm, or evaluation protocol that produces the claimed change. An equation is useful here only if it explains that mechanism.
Inspect the original paperClaims and evidence
A claim is source-linked only when the PDF page and matching excerpt are available.
- claim 01Paperraft inference
Read the brief interpretation
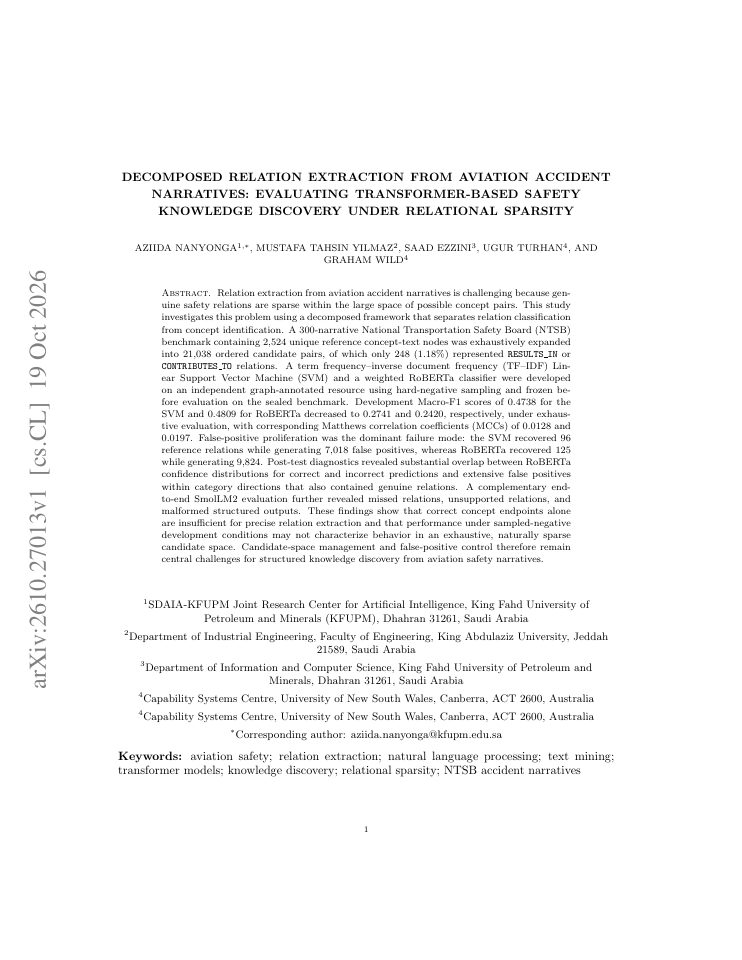
The method replaces end-to-end relation extraction with a decomposed pipeline: candidate concept pairs are enumerated first, then a TF-IDF Linear SVM or weighted RoBERTa classifier labels them as RESULTS_IN or CONTRIBUTES_TO. Cost is dominated by the candidate space (21,038 pairs from 300 narratives) and by quality: exhaustive evaluation collapsed Macro-F1 from ~0.47-0.48 in development to 0.24-0.27, with MCC near zero (0.013-0.020) and 7,018-9,824 false positives against 96-125 recovered true relations. What fails after adoption is precision at deployment scale: hard-negative sampled development scores did not transfer to exhaustive candidate evaluation, RoBERTa confidence distributions overlapped between classes, and false positives persisted even within valid relation directions, so known concept endpoints do not yield reliable extraction.
This is a Paperraft inference. It is not pinned to a verified PDF passage.
Inspect the source
Exposure map
Author findings, Paperraft interpretations, and the next check. Missing analysis never counts as evidence of safety.
quality
Still unknownWhich tasks improve, and which regress against the baseline?
compute and memory
Still unknownWhat memory, hardware, and total compute does the complete method require?
latency
Still unknownAre startup time, typical response time, and slow requests measured separately?
operations
Still unknownWhat must be monitored, maintained, and rolled back?
software compatibility
Still unknownDoes the implementation support your model, runtime, and hardware?
security
Still unknownWhat new data access, permissions, or trust boundaries does it introduce?
data and training
Still unknownWhat data preparation or training is required, and is it included in the cost?
reproducibility
Still unknownAre code, versions, inputs, and evaluation scripts available?
Continue the investigation
A reading guide for retrieval and RAG.
Editorial prompts, not findings from this paper or a validated test plan. Detailed analysis is still pending for the topics below.
What to inspect
Which retrieval and reranking stages change? Check whether supporting evidence is actually retrieved.
Plan a fair comparison
Can you freeze the corpus and questions, then compare answer quality and citation support against simple retrieval?
Questions for adoption
What happens when the answer is missing from the corpus or the indexed content changes?
Inside the paper
Preview the first 3 pages of the original PDF. Click the stack to turn the page.
The downloadable skill includes SKILL.md and evidence.json, with recorded findings and unanswered checks. TRY-IT.md adds a product test plan and a blank results sheet.
A reading aid for your agent. Findings still need validation.
Provisional research brief updated 2026-10-25. Paperraft has not reproduced this experiment.