For solo builders
A possible application for this research area. Paper-specific feasibility still needs a full-paper review.
Your self-hosted model spends too long generating answers token by token.
What you would change
Check whether a compatible draft model and serving integration exist before renting compute.
Try the idea on your product
A proposed first test. Set your budget and success criteria before running it.
Check whether a compatible draft model and serving integration exist before renting compute.
Compare against
The same target with speculation off, then your existing drafter if you have one.
- Locate the paper's implementation and check its license, model support, data needs, and hardware requirements. Stop here if you cannot obtain the required artifacts.
- Save a small set of representative product tasks and expected outcomes. Keep evaluation tasks out of any training or tuning, and choose quality and cost limits before running.
- Run the baseline and the proposed change on identical inputs. Keep other settings fixed and repeat paired runs to expose variation.
- Save per-task outputs, failures, timings, and all usage costs. Review regressions before expanding the test.
What to measure
Accepted draft length, tokens per second, tail latency, output quality, and total GPU cost.
When to keep it
Keep the change only if it meets your preselected quality and latency limits and improves the metric you care about after setup and operating costs. Otherwise retain the baseline. This is an exploration plan, not a validated recommendation.
Download test plan ↓abstract indexedPaperraft next step
Do not allocate compute yet.
This page uses the abstract and public adoption signal only. Request the deep report before relying on its recommendation.
Abstract-level screening only. Risks and infrastructure may not have been evaluated. This recommendation is not a reproduced result.- minimum test setup
- not reported
- published evidence setup
- not reported
- source-linked claims
- 0 of 2
- exposure checks
- 0 of 8
Why it was shortlisted
The technical change, research area, and reason it entered the archive.
- recommendation
- watch
- research area
- speculative decoding
- technical change
- Pipelined self-speculative decoding for looped transformers
- published
- 2026-09-15
The method is restricted to Looped Transformers, a niche architecture the reader is unlikely to run in production, so the claim is worth tracking but not actionable on constrained infrastructure today.
Central equations
Original equations, typeset for reading. Paperraft explanations connect the mechanism, its aim, and the evidence.
for every and the total depth . Then, the optimal proposal depths to minimize expected number of recurrent steps to commit a single token are
equation (8) · §5 Theoretical Analysis · proposed method
We implement LoopSpec by extending the SGLang serving engine (Zheng et al., 2024). All experiments are executed on an NVIDIA RTX PRO 6000 Blackwell GPU in BF16 precision using the Triton attention backend and the TinyGEMM backend provided by FlashInfer (Ye et al., 2025). Further SGLang implementation details are in Appendix B. We report speedup on wall-clock time and mean accepted length . Wall-clock time speedup is measured over the decoding phase, after the completion of prompt prefilling until the end of generation. We define as the average number of generated tokens produced per full model execution of recurrent steps:
equation (9) · §6 Experiments · metric
Let be a random prefix drawn from a fixed distribution over prefixes. Assume that there exist constants such that
equation (7) · §5 Theoretical Analysis · complexity
equations from arXiv HTML · fetched 2026-10-18
Claims and evidence
A claim is source-linked only when the PDF page and matching excerpt are available.
- claim 01Paperraft inference
Read the brief interpretation
LoopSpec replaces standard autoregressive decoding in Looped Transformers with a training-free self-speculative scheme in which early recurrent depths draft tokens, deeper depths optionally re-propose, and the full model verifies, pipelined so drafting overlaps verification. It costs additional implementation complexity in the decoding loop and extra compute for verification and the selective second proposal, though it requires no auxiliary draft model and no retraining. It can fail to deliver speedup if draft acceptance rates are low on the target workload, and it applies only to Looped Transformer architectures, which are not the mainstream open-weight models the reader is likely to deploy.
This is a Paperraft inference. It is not pinned to a verified PDF passage.
Inspect the source - claim 02Paperraft inference
The paper reports up to 6.83x inference speedup across diverse Looped Transformers on reasoning and coding benchmarks, with lossless decoding under greedy and sampling regimes.
This is a Paperraft inference. It is not pinned to a verified PDF passage.
Inspect the source
Exposure map
Author findings, Paperraft interpretations, and the next check. Missing analysis never counts as evidence of safety.
quality
Still unknownWhich tasks improve, and which regress against the baseline?
compute and memory
Still unknownWhat memory, hardware, and total compute does the complete method require?
latency
Still unknownAre startup time, typical response time, and slow requests measured separately?
operations
Still unknownWhat must be monitored, maintained, and rolled back?
software compatibility
Still unknownDoes the implementation support your model, runtime, and hardware?
security
Still unknownWhat new data access, permissions, or trust boundaries does it introduce?
data and training
Still unknownWhat data preparation or training is required, and is it included in the cost?
reproducibility
Still unknownAre code, versions, inputs, and evaluation scripts available?
Continue the investigation
A reading guide for speculative decoding.
Editorial prompts, not findings from this paper or a validated test plan. Detailed analysis is still pending for the topics below.
What to inspect
How are proposals verified, and what happens after rejection? Check the assumptions behind any quality guarantee.
Plan a fair comparison
Can you compare the same target model with speculation off and on, including proposal and verification time?
Questions for adoption
Which draft model or prediction heads are needed, and how does acceptance change with the workload?
Inside the paper
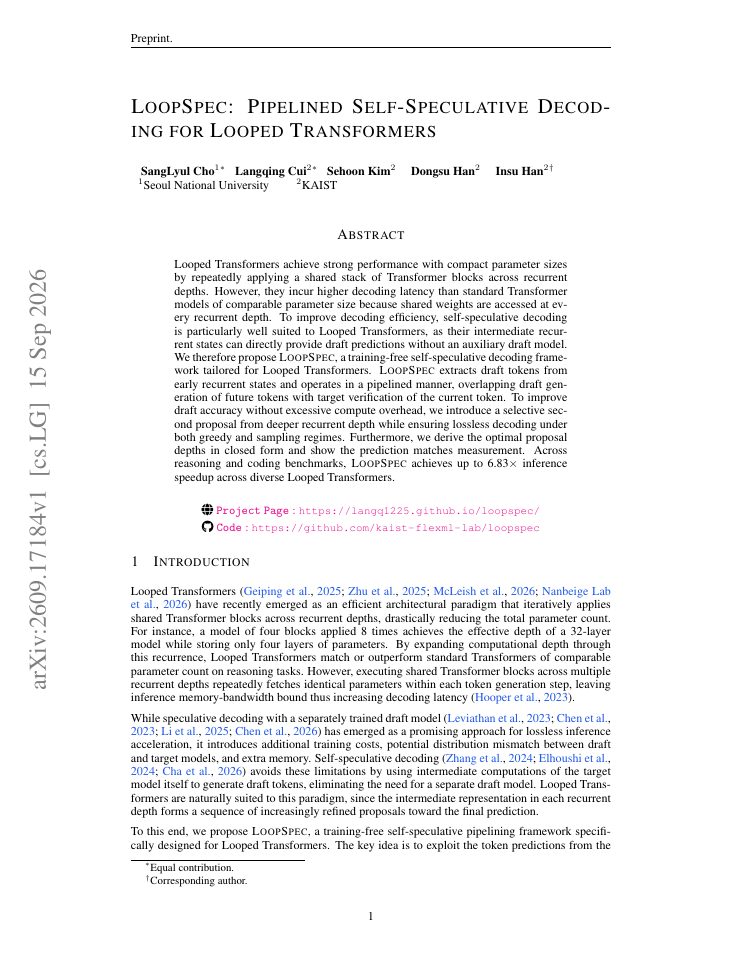
Preview the first 3 pages of the original PDF. Click the stack to turn the page.
The downloadable skill includes SKILL.md and evidence.json, with recorded findings and unanswered checks. TRY-IT.md adds a product test plan and a blank results sheet.
A reading aid for your agent. Findings still need validation.
Provisional research brief updated 2026-10-18. Paperraft has not reproduced this experiment.