For solo builders
A possible application for this research area. Paper-specific feasibility still needs a full-paper review.
An agent reads external documents or tool responses that may contain malicious instructions.
What you would change
Replay attacks and legitimate lookalikes in an isolated copy of your agent workflow.
Try the idea on your product
A proposed first test. Set your budget and success criteria before running it.
Replay attacks and legitimate lookalikes in an isolated copy of your agent workflow.
Compare against
Your existing checks with the same tasks, permissions, and tool responses.
- Locate the paper's implementation and check its license, model support, data needs, and hardware requirements. Stop here if you cannot obtain the required artifacts.
- Save a small set of representative product tasks and expected outcomes. Keep evaluation tasks out of any training or tuning, and choose quality and cost limits before running.
- Run the baseline and the proposed change on identical inputs. Keep other settings fixed and repeat paired runs to expose variation.
- Save per-task outputs, failures, timings, and all usage costs. Review regressions before expanding the test.
What to measure
Successful attacks missed, legitimate actions blocked, detection delay, and review cost.
When to keep it
Keep the change only if it meets your preselected quality and latency limits and improves the metric you care about after setup and operating costs. Otherwise retain the baseline. This is an exploration plan, not a validated recommendation.
Download test plan ↓abstract indexedPaperraft next step
Do not allocate compute yet.
This page uses the abstract and public adoption signal only. Request the deep report before relying on its recommendation.
Abstract-level screening only. Risks and infrastructure may not have been evaluated. This recommendation is not a reproduced result.- minimum test setup
- not reported
- published evidence setup
- not reported
- source-linked claims
- 0 of 1
- exposure checks
- 0 of 8
Why it was shortlisted
The technical change, research area, and reason it entered the archive.
- recommendation
- watch
- research area
- safety and guardrails
- technical change
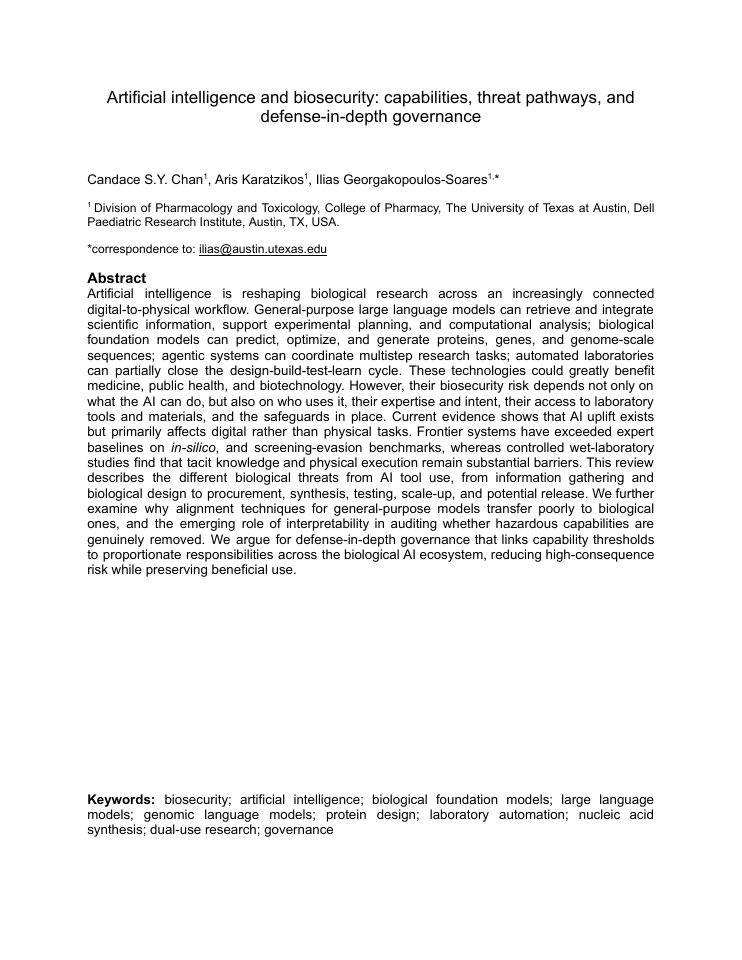
- Defense-in-depth governance for biological AI
- published
- 2026-09-14
This is a policy and threat-modeling survey with no deployable technique or quantified performance gain, so it is relevant context for teams handling biological models but offers nothing to implement on constrained infrastructure today.
About the technical core
arXiv has no HTML rendering for this paper.
When reading the methods, identify the rule, algorithm, or evaluation protocol that produces the claimed change. An equation is useful here only if it explains that mechanism.
Inspect the original paperClaims and evidence
A claim is source-linked only when the PDF page and matching excerpt are available.
- claim 01Paperraft inference
Read the brief interpretation
The paper is a governance review, not an engineering method: it proposes replacing ad-hoc or absent biosecurity controls with tiered, capability-threshold-linked responsibilities across the biological AI stack, rather than replacing any specific model component. Adopting its framework costs organizational effort—capability evaluations, screening-evasion benchmarks, and audit processes—rather than GPU memory or latency, though any applied safeguards can add refusal overhead and false-positive blocking of legitimate queries. It can fail because alignment techniques transfer poorly to biological foundation models, so hazardous capabilities may persist undetected despite applied mitigations, and current uplift evidence is largely in-silico, meaning thresholds may be miscalibrated.
This is a Paperraft inference. It is not pinned to a verified PDF passage.
Inspect the source
Exposure map
Author findings, Paperraft interpretations, and the next check. Missing analysis never counts as evidence of safety.
quality
Still unknownWhich tasks improve, and which regress against the baseline?
compute and memory
Still unknownWhat memory, hardware, and total compute does the complete method require?
latency
Still unknownAre startup time, typical response time, and slow requests measured separately?
operations
Still unknownWhat must be monitored, maintained, and rolled back?
software compatibility
Still unknownDoes the implementation support your model, runtime, and hardware?
security
Still unknownWhat new data access, permissions, or trust boundaries does it introduce?
data and training
Still unknownWhat data preparation or training is required, and is it included in the cost?
reproducibility
Still unknownAre code, versions, inputs, and evaluation scripts available?
Continue the investigation
A reading guide for safety and guardrails.
Editorial prompts, not findings from this paper or a validated test plan. Detailed analysis is still pending for the topics below.
What to inspect
Which assumptions does the proposed method need, and where might your workload violate them?
Plan a fair comparison
Identify the baseline, metric, dataset, and experimental settings in the paper. Which can you match?
Questions for adoption
What implementation and evaluation artifacts are available, and what would you need to supply?
Inside the paper
Preview the first 3 pages of the original PDF. Click the stack to turn the page.
The downloadable skill includes SKILL.md and evidence.json, with recorded findings and unanswered checks. TRY-IT.md adds a product test plan and a blank results sheet.
A reading aid for your agent. Findings still need validation.
Provisional research brief updated 2026-10-18. Paperraft has not reproduced this experiment.